Guardrails for
LLM answers.
GroundLens checks an LLM answer against its sources without a model, decides PASS, REVIEW or FAIL under your policy, and keeps a signed record.
Free, Apache-2.0No modelNo networkPython 3.10+
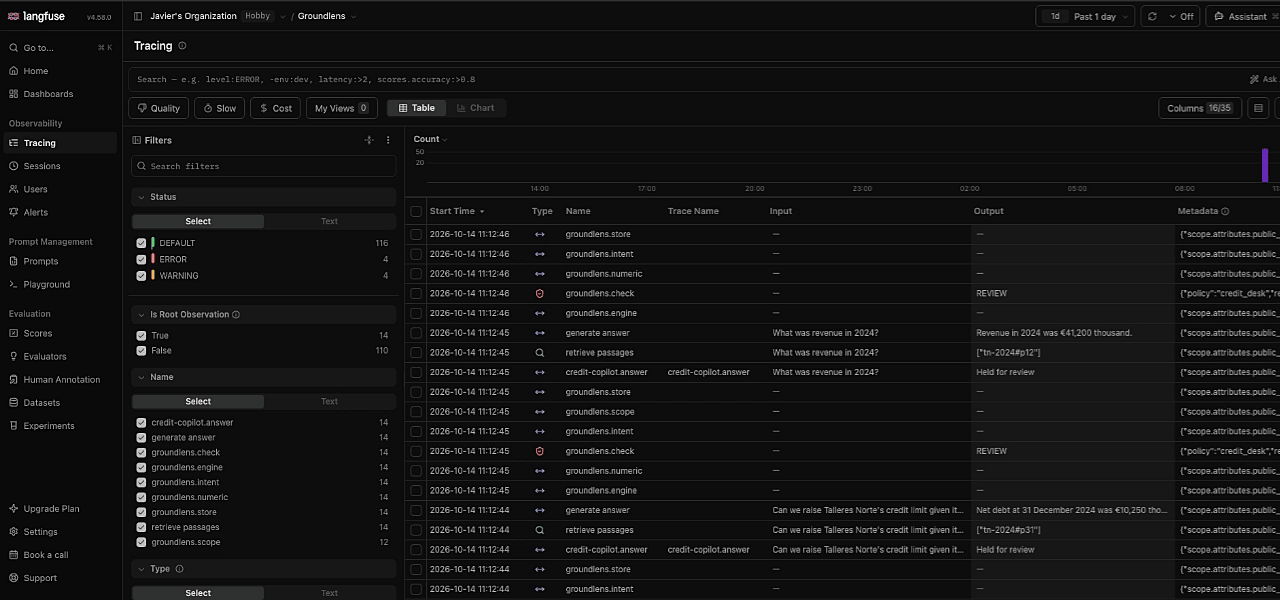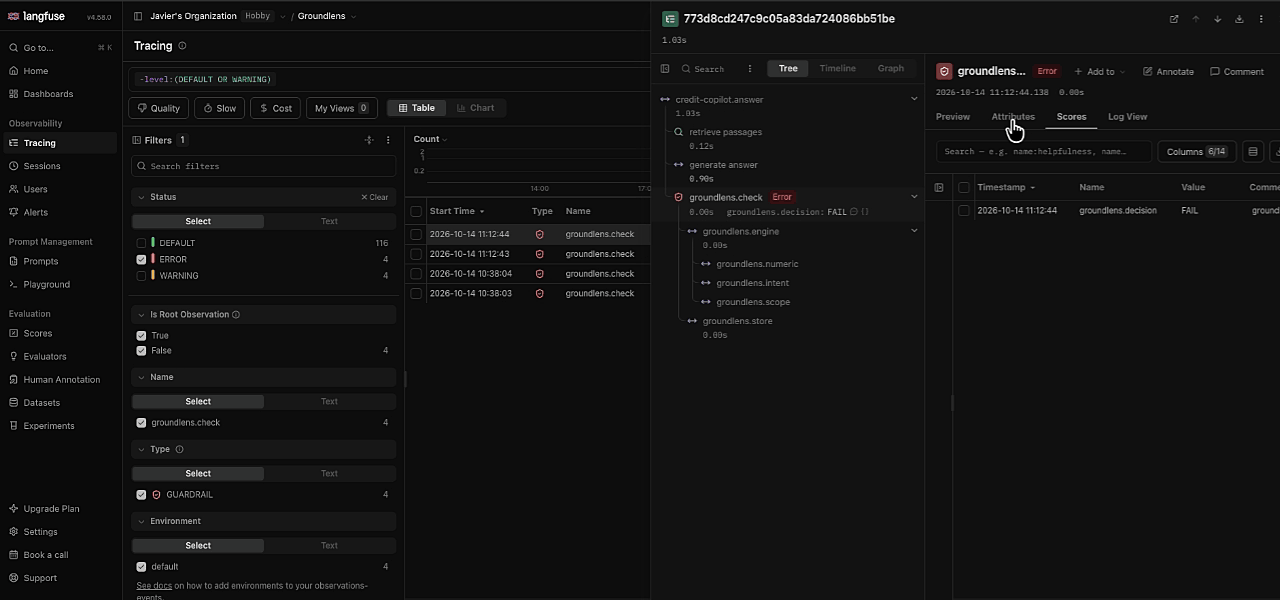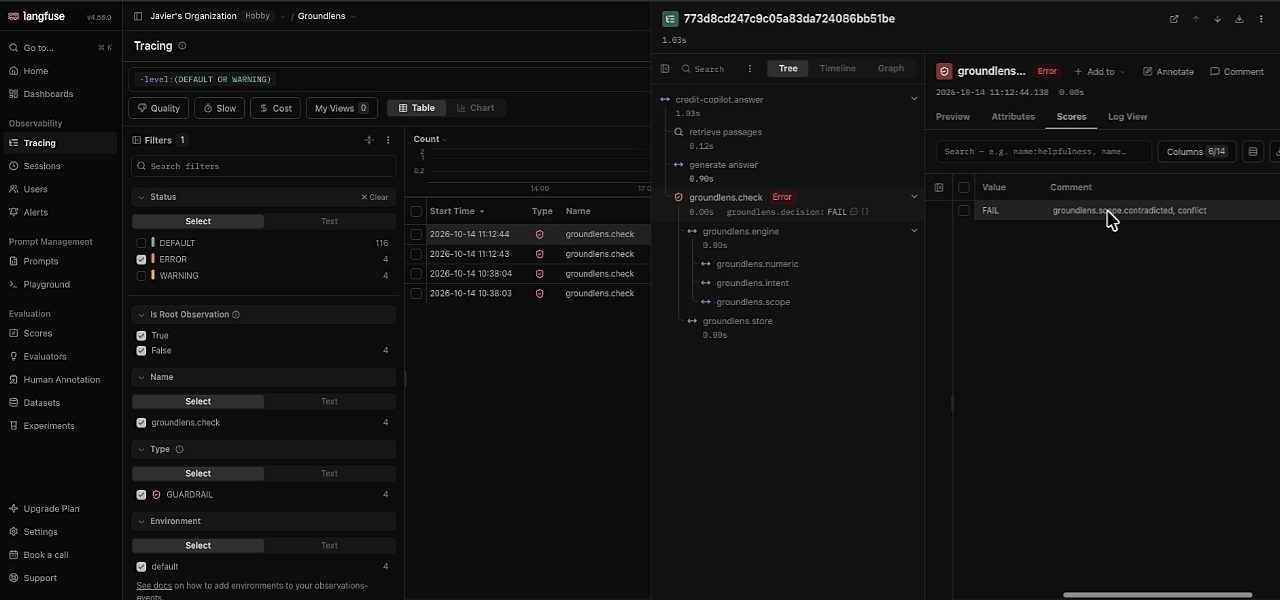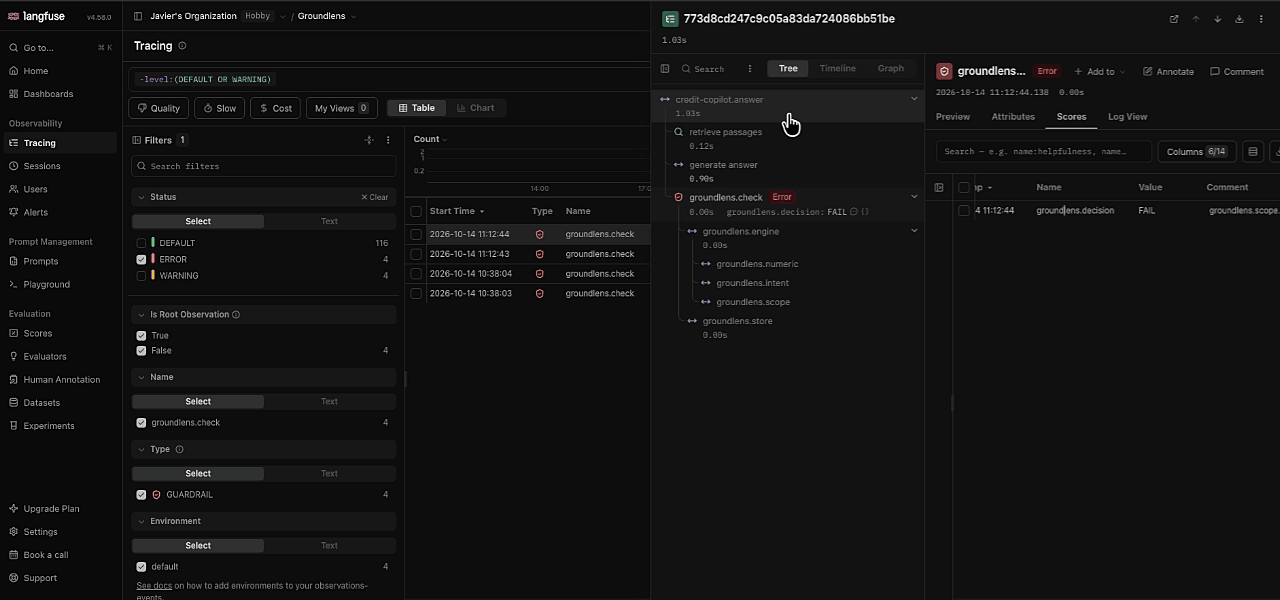
Each check inside the Langfuse trace of the answer it checked: the decision, the reasons and the time each step took.
Why GroundLens
A decision you can defend,
not another score.
First, with no LLM judge needed. The same answer gets the same result on every machine.
PASS, REVIEW or FAIL, with reasons, hashed and chained before the decision returns.
You know the share of wrong answers among those that passed, with a confidence interval.
One implementation for Python and the command line, on Linux, macOS and Windows.
How it works
Five steps between the answer
and anyone who acts on it.
Your model writes an answer from the passages your retriever found. Before anyone acts on it, GroundLens:
- Checks every figure. It must be in the passages, or follow from figures that are: a sum, a difference, a ratio, a percentage change, compared as exact fractions in the locale and units the documents use.
- Checks where each figure came from. A real figure taken from another company, contract or year fails.
- Checks it is what was asked. A percentage when the question asked for a percentage; euros when it asked for euros.
- Applies your policy. PASS, REVIEW or FAIL, with the reasons a reviewer reads first.
- Signs and stores the record before it returns the decision. No stored record, no decision.
import groundlens as gl

verifier = gl.Verifier(sink=gl.sinks.jsonl("records/"))
record = verifier.check(
    answer="Revenue was €42.1 million.",
    passages=["Revenue reached €41.2 million."],
)
print(record.decision, record.reasons)
FAIL ['c2: groundlens.numeric contradicted:
€42.1 million not in sources; nearest 41200000 EUR
in ctx-0 (relative distance 0.021)']| For | Teams whose LLM answers carry figures: finance, credit, insurance, legal, procurement, reporting. |
| Runs | In your process. Python 3.10+, Linux, macOS, Windows. No server, no account, no API key, no model, no network. |
| Works with | Langfuse, Grafana and any OpenTelemetry backend, MCP clients, your LLM judge (OpenAI-compatible, Azure OpenAI, Bedrock), AWS KMS, Azure Key Vault, PKCS#11 HSMs, S3 Object Lock, Azure Blob, Postgres. |
| Engine | Rust. One implementation: the same answer gives the same content hash on every machine. |
| Price | Free. Apache-2.0, all of it. |
Already running an LLM-as-judge?
Keep it. Let GroundLens check first.
A FAIL never reaches the judge. Your judge only sees the answers the exact checks could not reject, and it can escalate an answer, never pass one. Every call is recorded: the template, the hash of the prompt, the model that answered and the hash of its reply.
What it catches, and what it does not
Exact where it can be.
Clear about where it cannot.
| Error in the answer | Caught by |
|---|---|
| A figure that is not in the passages | FAIL exact check |
| Wrong arithmetic: a sum, ratio or percentage change that does not follow | FAIL exact check |
| A real figure from another company, contract or year | FAIL scope check |
| A figure of another kind or unit than the question asked for | REVIEW intent check |
| A request that does not say which entity it is about, when the policy requires it | REVIEW policy |
| A record edited, deleted or reordered after the fact | detected record verify, offline |
| A real figure from the wrong row of the right table | your judge |
| A sentence the passages never say | your judge |
| A fact that is wrong in the passages themselves | nothing it checks against your passages, not the world |
Works with
Where you already look.
Langfuse
Each check in the trace that produced the answer, as a guardrail observation, with the decision as a categorical score.
pip install "groundlens[langfuse]"Grafana and OpenTelemetry
Spans and metrics through the providers your application already uses, and a ready dashboard.
pip install "groundlens[otel]"MCP
Any MCP client gets three tools: verify_answer, verify_run, verify_records.
pip install "groundlens[mcp]"Your judge
OpenAI and any compatible server (vLLM, Ollama, your gateway), Azure OpenAI, Bedrock. You pass the client you already use.
gl.judges.openai_compatible(client, model)Your keys
Records signed in AWS KMS, Azure Key Vault or a PKCS#11 HSM. The key never leaves it.
gl.signers.aws_kms(client, key_id)Your storage
S3 Object Lock, Azure Blob, Postgres or JSON Lines. Written once, never overwritten.
gl.sinks.s3_object_lock(client, bucket)For regulated teams
Evidence an auditor can check
without your software.
The eu_ai_act_high_risk_v1 policy maps each decision to Regulation (EU) 2024/1689. It produces evidence for those controls; it does not make a system compliant on its own.
| FAIL | Art. 15(1) accuracy |
| REVIEW | Art. 14(4)(a) human oversight |
| every record | Art. 12(1) record keeping |
Every record carries a content hash, the hash of the record before it and a signature. Anyone can check a whole log offline with the public key alone, with groundlens record verify or with glv, a single binary that needs no Python. groundlens measure estimates the share of wrong answers among those that passed, from a small sample your team labels.
FAQ
Before you install.
Is GroundLens a hallucination detector?
It is narrower and stricter. It checks the figures in an answer against the passages the answer was written from, and the policy decides what a mismatch means. For sentences without figures, connect your own LLM judge.
Does it need a GPU, a model or an API key?
No. The checks are exact and run in your process in about a millisecond. A judge is optional, and it is the model you already use.
Does any data leave my machine?
No. The engine has no network code. Other systems are reached only through clients you create and pass in.
Is it deterministic?
The checks are: the same answer, passages and policy give the same content hash on Linux, macOS and Windows. A judge is not, and the record says so.
How is it different from Guardrails AI, NeMo Guardrails, Ragas or DeepEval?
Those score or filter answers, mostly with a model. GroundLens decides with exact checks, under a policy you version, and leaves a signed record of why. It works next to them.
Does it work with LangChain, LlamaIndex or my own stack?
Yes. It is one call after your model answers: verifier.check(answer=..., passages=...).
What does it cost?
The software costs nothing. Apache-2.0: engine, checks, policies, connectors, command line and MCP server. Measuring it on your answers and running it in your cloud is a paid service: write to javier@groundlens.dev.
For agents
Readable by people and by models.
Every page here has a Markdown twin, and llms.txt says when to use GroundLens and when not to. An agent can also call it directly over MCP.
- /llms.txtwhen to use it, how to call it
- /index.mdthis page as Markdown
- /compare.mdGroundLens and other tools
- readthedocsguides and reference
- pypipip install groundlens
io.github.groundlens-dev/groundlensMCP registry