hallucination-benchmark
An open evaluation dataset for hallucination triage methods.
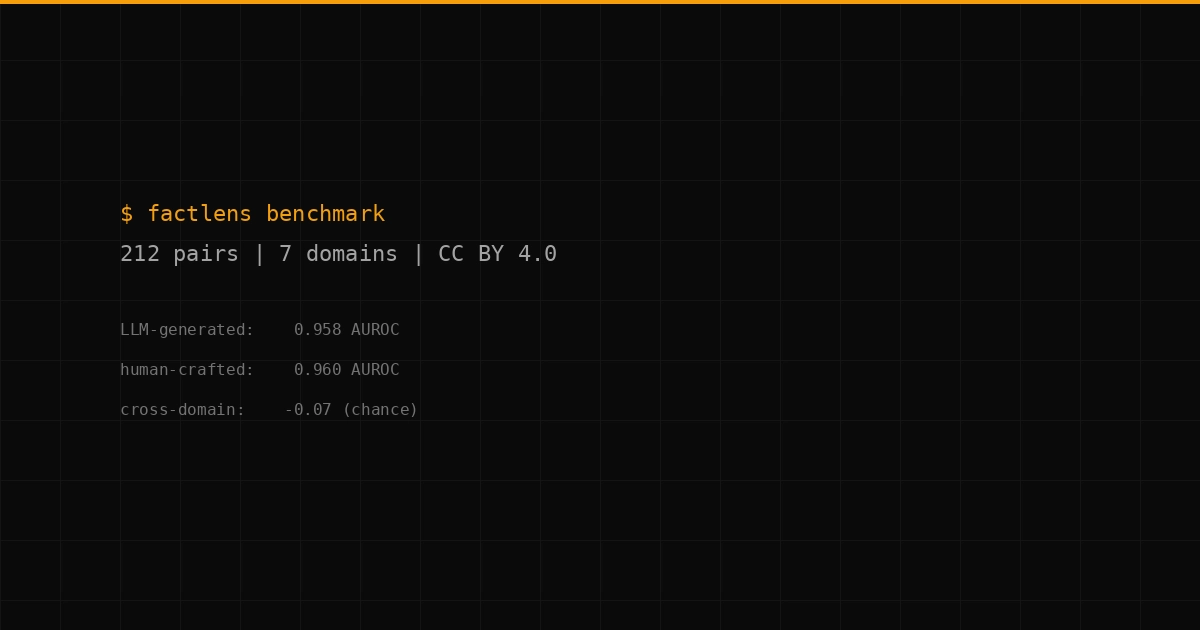
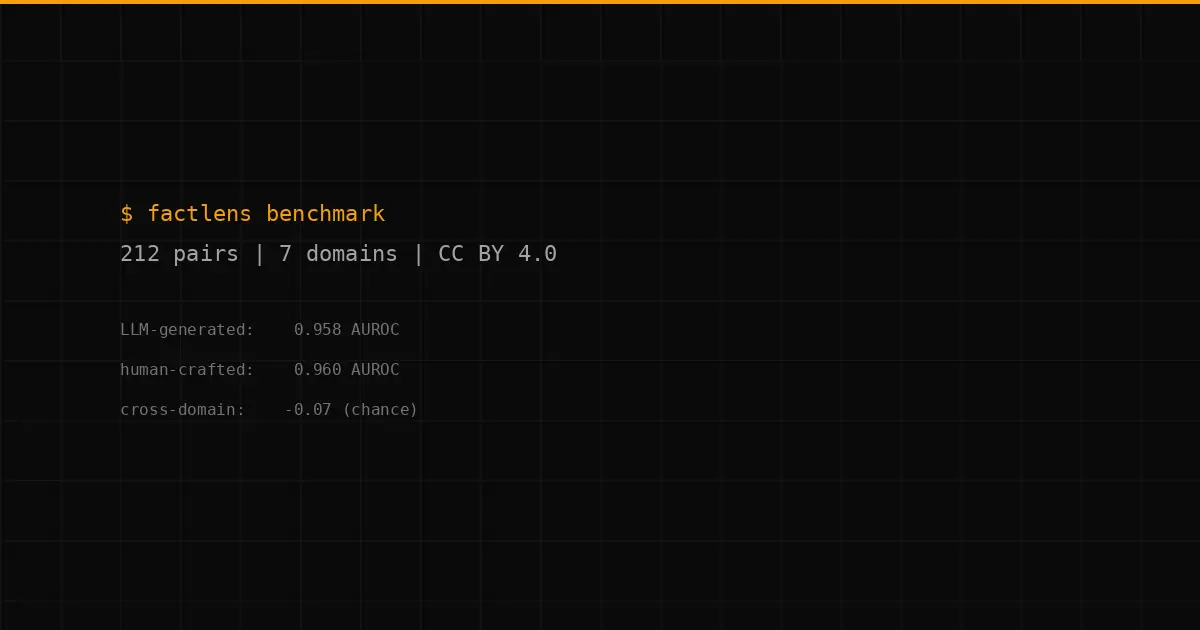
212 question-response pairs across nine knowledge domains. Each pair has a grounded response and a human-written confabulation — invented institutions, fabricated mechanisms, fictional terminology written by a person, not generated by an LLM.
Provenance. All 212 confabulations were written by a single non-expert author across all nine domains, from memory, without consulting any source. Two additional reviewers checked them for plausibility, domain appropriateness and length compliance, and verified the grounded responses against authoritative sources. Because there is one confabulator, no inter-annotator agreement statistic is available, and person-specific style is a live limitation of the dataset rather than a controlled variable.
Key findings, revised. Two AUROC figures reported here in early 2026 were withdrawn in July 2026 and must not be cited: they did not survive an authorship-matched control. With the grounded and the confabulated text written by the same person, the same detectors fall to 0.660 (logistic), 0.675 (MLP) and 0.606 (DGI). The apparent skill was authorship, not grounding. Cross-domain detection collapses to chance. The dataset stays useful precisely because it makes that measurable.
GitHub repository · Paper (PDF)
← Back to projects